How ChatGPT Actually Picks Sources (And Why It Matters)
- Post By: FAISAL MUSTAFA
- Published: July 27, 2026
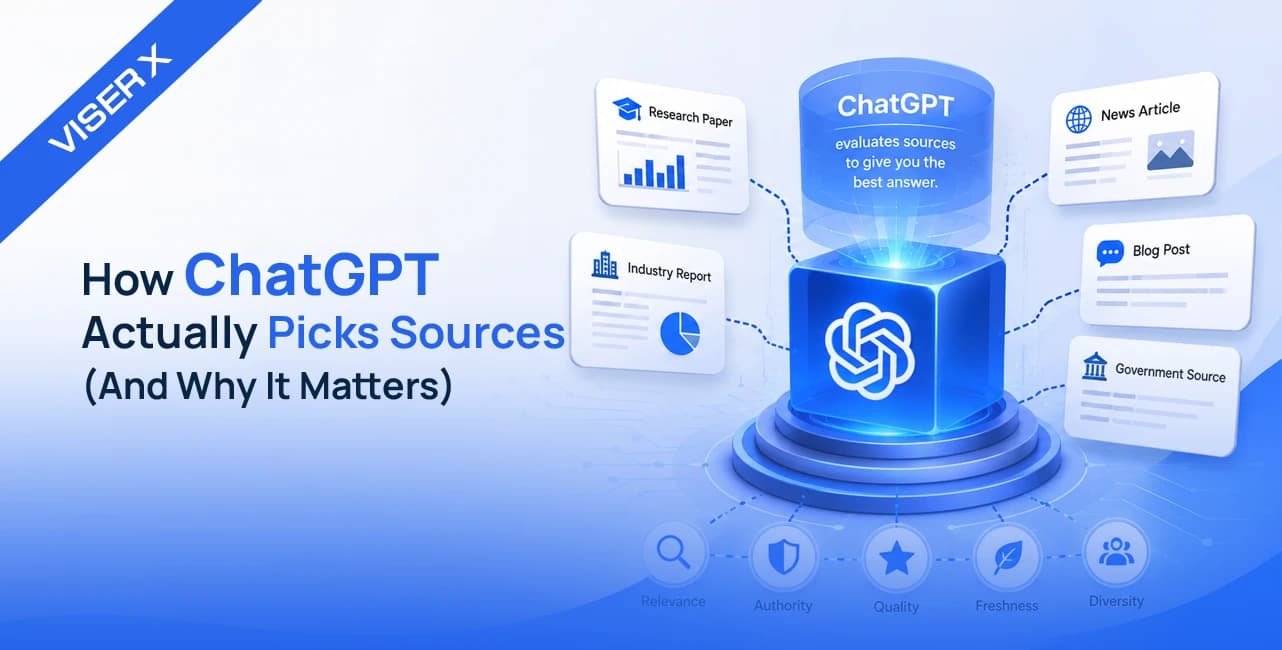


ChatGPT picks sources through a retrieval, ranking, and citation-selection pipeline built on top of Bing's index. A page has to survive all three stages, and most don't. Being indexed isn't enough, and ranking well isn't enough. The page also has to answer the exact sub-query cleanly enough that the model chooses it over all other results.
Whether you need comprehensive SEO, data-driven PPC campaigns, or full-funnel content strategies, taking help from a reliable digital marketing agency in Bangladesh can bridge the gap between traditional search visibility and generative AI recommendations.
How ChatGPT actually picks sources comes down to two decisions made before you ever see an answer: whether the model searches the web at all, and, if it does, which pages survive a three-step filter that throws out most of what it finds.
Roughly a third of prompts never trigger a live search, so nothing gets read or cited. When a search does fire, ChatGPT breaks your question into sub-queries, pulls pages mostly from Bing's index, ranks them for relevance and trust, then cites a small handful.
Let's walk through each stage of that pipeline and discover what actually moves a page from "retrieved" to "cited."
The Two-Mode Problem (Why Most Queries Never Retrieve a Source at All)
ChatGPT runs in two modes: parametric memory (answering from training data, no search) and browse mode (searching the web and citing sources). Roughly a third of prompts never leave parametric memory.
This is the part most content teams skip past. Before ChatGPT can cite your page, it has to decide that the question is worth searching for. If it doesn't, your page was never in the running, no matter how well it's written or how well it ranks on Google.
In parametric memory mode, ChatGPT answers straight from what it learned during training. No fetch happens, no citations appear.
The answer might be accurate, outdated, or flatly wrong, but there's no source link attached either way. Independent testing on real ChatGPT traffic found that about 31% of prompts trigger at least one search, meaning most everyday questions are still answered from memory alone.
Search frequency also varies widely by topic: local questions trigger a search around 59% of the time, according to Search Engine Land.
Browse mode is where the real competition starts. Once ChatGPT decides a query needs current information, it rewrites your question into two to four sub-queries (query fan-out), reads back a set of candidate pages, and only then builds an answer with citations attached. This is the only mode where your content has any chance of appearing as a linked source.
How to Tell Which Mode Your Target Queries Are Using
Run your target questions through ChatGPT yourself and check for citation markers. If the answer has no linked sources, it came from memory rather than the web.
The fastest way to check is to open ChatGPT in an incognito session and type the exact questions your customers would ask. Look for two things: citation markers or linked source names (browse mode fired), or hedging phrases like "as of my last update" (the model stayed in memory).
Comparisons, recommendations, pricing, and anything time-sensitive ("best," "cost of," "vs," "near me") trigger search far more reliably than pure definition questions. If your priority keywords rarely get searched, no amount of on-page optimization will get you cited on them. That's a targeting problem, not a content problem, worth fixing first.
Where ChatGPT Actually Pulls Pages From (The Four Source Tiers)
ChatGPT's web search draws mainly from Bing's index, leaning heavily on four recurring source types: reference sites, community platforms, established media, and commerce or review platforms.
ChatGPT's search has historically run on Bing's infrastructure, not Google's. That catches a lot of businesses off guard, because it means Bing Webmaster Tools matters here in a way most SEO teams never check.
If Bing hasn't indexed your page cleanly, browse mode is far less likely to ever see it, no matter how it performs on Google.
Once pages are pulled from that index, citation data shows a clear pattern in what tends to make the cut:
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
Independent tracking backs this up. An analysis of nearly 600,000 citation events found that Wikipedia and Reddit alone account for roughly 12-13% of all ChatGPT citations each, according to Similarweb.
Separate tracking from Ahrefs puts Reddit at the very top of ChatGPT's most-cited domains overall. Outside that top handful, no single domain captures much share, so the rest of the web competes for a long tail of citation slots rather than a single dominant spot.
Owned brand content, your own blog, and service pages sit outside all four tiers by default. That doesn't mean it never gets cited. It means it has to work harder to prove the same signals a Wikipedia page or Reddit thread gets almost automatically: neutral framing, specific facts, and a structure the model can lift cleanly.
The Three-Stage Citation Pipeline (Why Retrieval Doesn't Equal Citation)
ChatGPT's citation process runs through retrieval, ranking, and citation selection. A page can pass the first two stages and still get cut at the third.
This is the single biggest misunderstanding in AI visibility right now. Teams check whether ChatGPT "found" their page, see that it did, and assume the job is done. It isn't.
Retrieval is just the entry ticket. Of the 548,534 retrieved pages in the AirOps study mentioned earlier, only 15% ever appeared in a final answer. The other 85% were read, evaluated, and quietly dropped, research covered by Search Engine Land.
Stage 1 - Retrieval (Can ChatGPT Find Your Page?)
Retrieval depends on whether your page is indexed by Bing and whether it matches the wording of the sub-queries ChatGPT generates, including ones you never directly targeted.
This stage works like traditional indexing. If Bing hasn't crawled and indexed your page, it can't be retrieved, full stop. But retrieval also depends on fan-out. ChatGPT doesn't just search for your exact phrase; it also generates related sub-questions and searches for those too.
One large-scale study found 89.6% of prompts generated two or more fan-out queries, and a third of all cited pages were pulled in through a fan-out query rather than the original question, per research covered by Search Engine Land.
A page can get cited for a question it never wrote toward, simply because it answered a related sub-question well.
Stage 2 - Ranking (Will Your Page Score High Enough?)
Ranking weighs relevance, authority, and structure, and while a high Google ranking correlates with a better shot at citation, it doesn't guarantee one.
Once a batch of pages is retrieved, ChatGPT scores them for how well they answer the sub-query, how trustworthy the domain appears, and how easily the content can be lifted. Pages ranking #1 on Google were cited about 3.5 times more often than pages outside Google's top 20, based on the same AirOps dataset.
But that's a correlation, not a rule. Plenty of pages with strong Google rankings never get pulled into an AI answer, because ChatGPT's ranking pass runs its own math on top of Bing's index, not Google's results.
Stage 3 - Citation Selection (Will ChatGPT Actually Link to You?)
Citation selection is the final cut, where the model picks the specific sentence-level facts it will use and decides which source earns the visible link.
This is where most of the retrieved and ranked pages are still dropped. The model isn't choosing a source; it's choosing individual facts, then attaching the source that supplied the cleanest version of that fact.
A page buried in vague formatting often loses out to clean, structured data, underscoring the importance of custom website development in delivering content that search models can easily extract. Only three to six citations typically appear per response, regardless of how many pages made it through the first two stages.
What This Means for Your Content (Without Repeating Generic AEO Advice)
The fix isn't "write better content." It's making sure your page survives all three stages: indexed cleanly on Bing, answering fan-out questions you haven't thought of, and stating facts in standalone sentences the model can lift without editing.
Most AEO advice stops at "use headers and answer questions clearly." That's true but incomplete, as it addresses only Stage 3. Here's what matters at each stage:
- For retrieval: Start by conducting a comprehensive SEO audit to confirm your site is indexed in Bing Webmaster Tools; skipping this simple check creates a permanent blocker for AI citations.
- For ranking: Cover the sub-questions around your main topic, not just the topic itself, since a third of citations come from fan-out queries.
- For citation selection: Write each section's answer as one clean, self-contained sentence near the top. A model extracting a fact under time pressure takes the sentence that needs no editing.
This is also where third-party proof does work; your own site can't. A stat published on your blog reads as a claim.
The same stat, picked up by an industry outlet, reads as consensus, which is why a robust online reputation management strategy helps build the third-party trust signals that LLMs look for. Brands running a coordinated SEO strategy alongside off-site proof building all three stages more consistently than those optimizing on-page content alone.
A Note on What We Don't Know (Epistemic Honesty as a Content Strategy)
OpenAI hasn't published the exact ranking formula, weightings shift between model updates, and studies measure different query sets, so treat any specific percentage as a directional signal, not a fixed rule.
Nobody outside OpenAI has the actual ranking weights that ChatGPT uses at Stage 2, and any guide that states they are fixed numbers is guessing.
The studies cited here, including the AirOps retrieval data and Similarweb's citation breakdowns, are large and directionally consistent, but they're snapshots of specific query sets and time windows, not a leaked algorithm.
Citation share for individual domains has also shifted fast. Reddit's citation share reportedly swung from roughly 60% down to 10% of prompt responses in a two-week window in late 2025, per tracking reported by PR Newswire.
Treat every number here as a pattern to plan around, not a permanent target.
What This Changes About How You Should Approach AI Visibility
Stop measuring success by whether ChatGPT can find your page. Start measuring whether it survives ranking and gets chosen at citation, since those are two different fights with two different fixes.
Most teams still track AI visibility the way they track Google rankings: check whether the page shows up and call it a win. That's measuring Stage 1 in a three-stage process, and Stage 1 is the easiest one to pass.
The real work is structuring content to win Stage 2 fan-out coverage and Stage 3 fact-level extraction, and building the off-site proof that gives ChatGPT a reason to trust your version of a fact over a competitor's.
This is a maintenance job, not a one-time fix. Citation patterns shift as models update and Bing reindexes, so a page cited this quarter can quietly lose that spot next quarter without any change on your end.
Teams that treat AI visibility as an ongoing system, checked on a schedule, and back it up with comprehensive digital marketing services, are the ones still showing up a year from now.
VISER X builds that system as part of its digital marketing services, pairing technical indexing work with the content structure and off-site proof that this pipeline rewards.
Frequently Asked Questions
Does ChatGPT browse the internet for every query?
No. ChatGPT searches the web for only a portion of prompts, roughly a third based on independent testing, and answers the rest from training data with no retrieval at all.
Is ChatGPT using Google or Bing to find sources?
ChatGPT's web search has primarily relied on Bing's index, not Google's, which is why being well-indexed and well-structured on Bing matters for citations, separate from Google rankings.
Why does ChatGPT cite Reddit but never YouTube?
ChatGPT's retrieval process reads and extracts text, so it favors easily parsed pages like Reddit threads and Wikipedia articles. Video is harder for a text-retrieval pipeline to extract facts from, so YouTube appears far less often in citations.
What is the difference between being mentioned and being cited by ChatGPT?
A mention comes from training memory; your brand's name appears with no link. A citation only happens in browse mode and includes a clickable link back to the source page.
Does ranking #1 on Google guarantee a ChatGPT citation?
No. Pages ranking #1 on Google get cited about 3.5 times as often as lower-ranked pages, but ChatGPT runs its own ranking pass on top of Bing's index, so a top Google spot doesn't guarantee anything.
What is query fan-out, and why does it matter for my content?
Query fan-out is when ChatGPT breaks one question into several sub-questions before searching. A third of all cited pages get pulled in through a sub-question, not the original query, so content that only answers the headline topic misses real citation opportunities.
Why do 85% of retrieved pages never get cited?
Retrieval is only the first of three stages. A page can be indexed and pulled into the candidate pool, then still lose out at ranking or citation selection to a page that states the same fact more directly or comes from a more trusted source